Introduction
Part 4 showed how RLHF teaches a language model what people prefer. People compare pairs of responses, a reward model learns to predict their choices with the Bradley-Terry model, and PPO trains the policy to maximize that reward while a KL penalty keeps it close to a frozen reference model. It works, but it is heavy. Stage 3 alone keeps four LLMs in memory, generates new responses at every iteration, and depends on many hyperparameters. And all of this is done to optimize a reward model that is itself only an approximation of the preferences we actually collected.
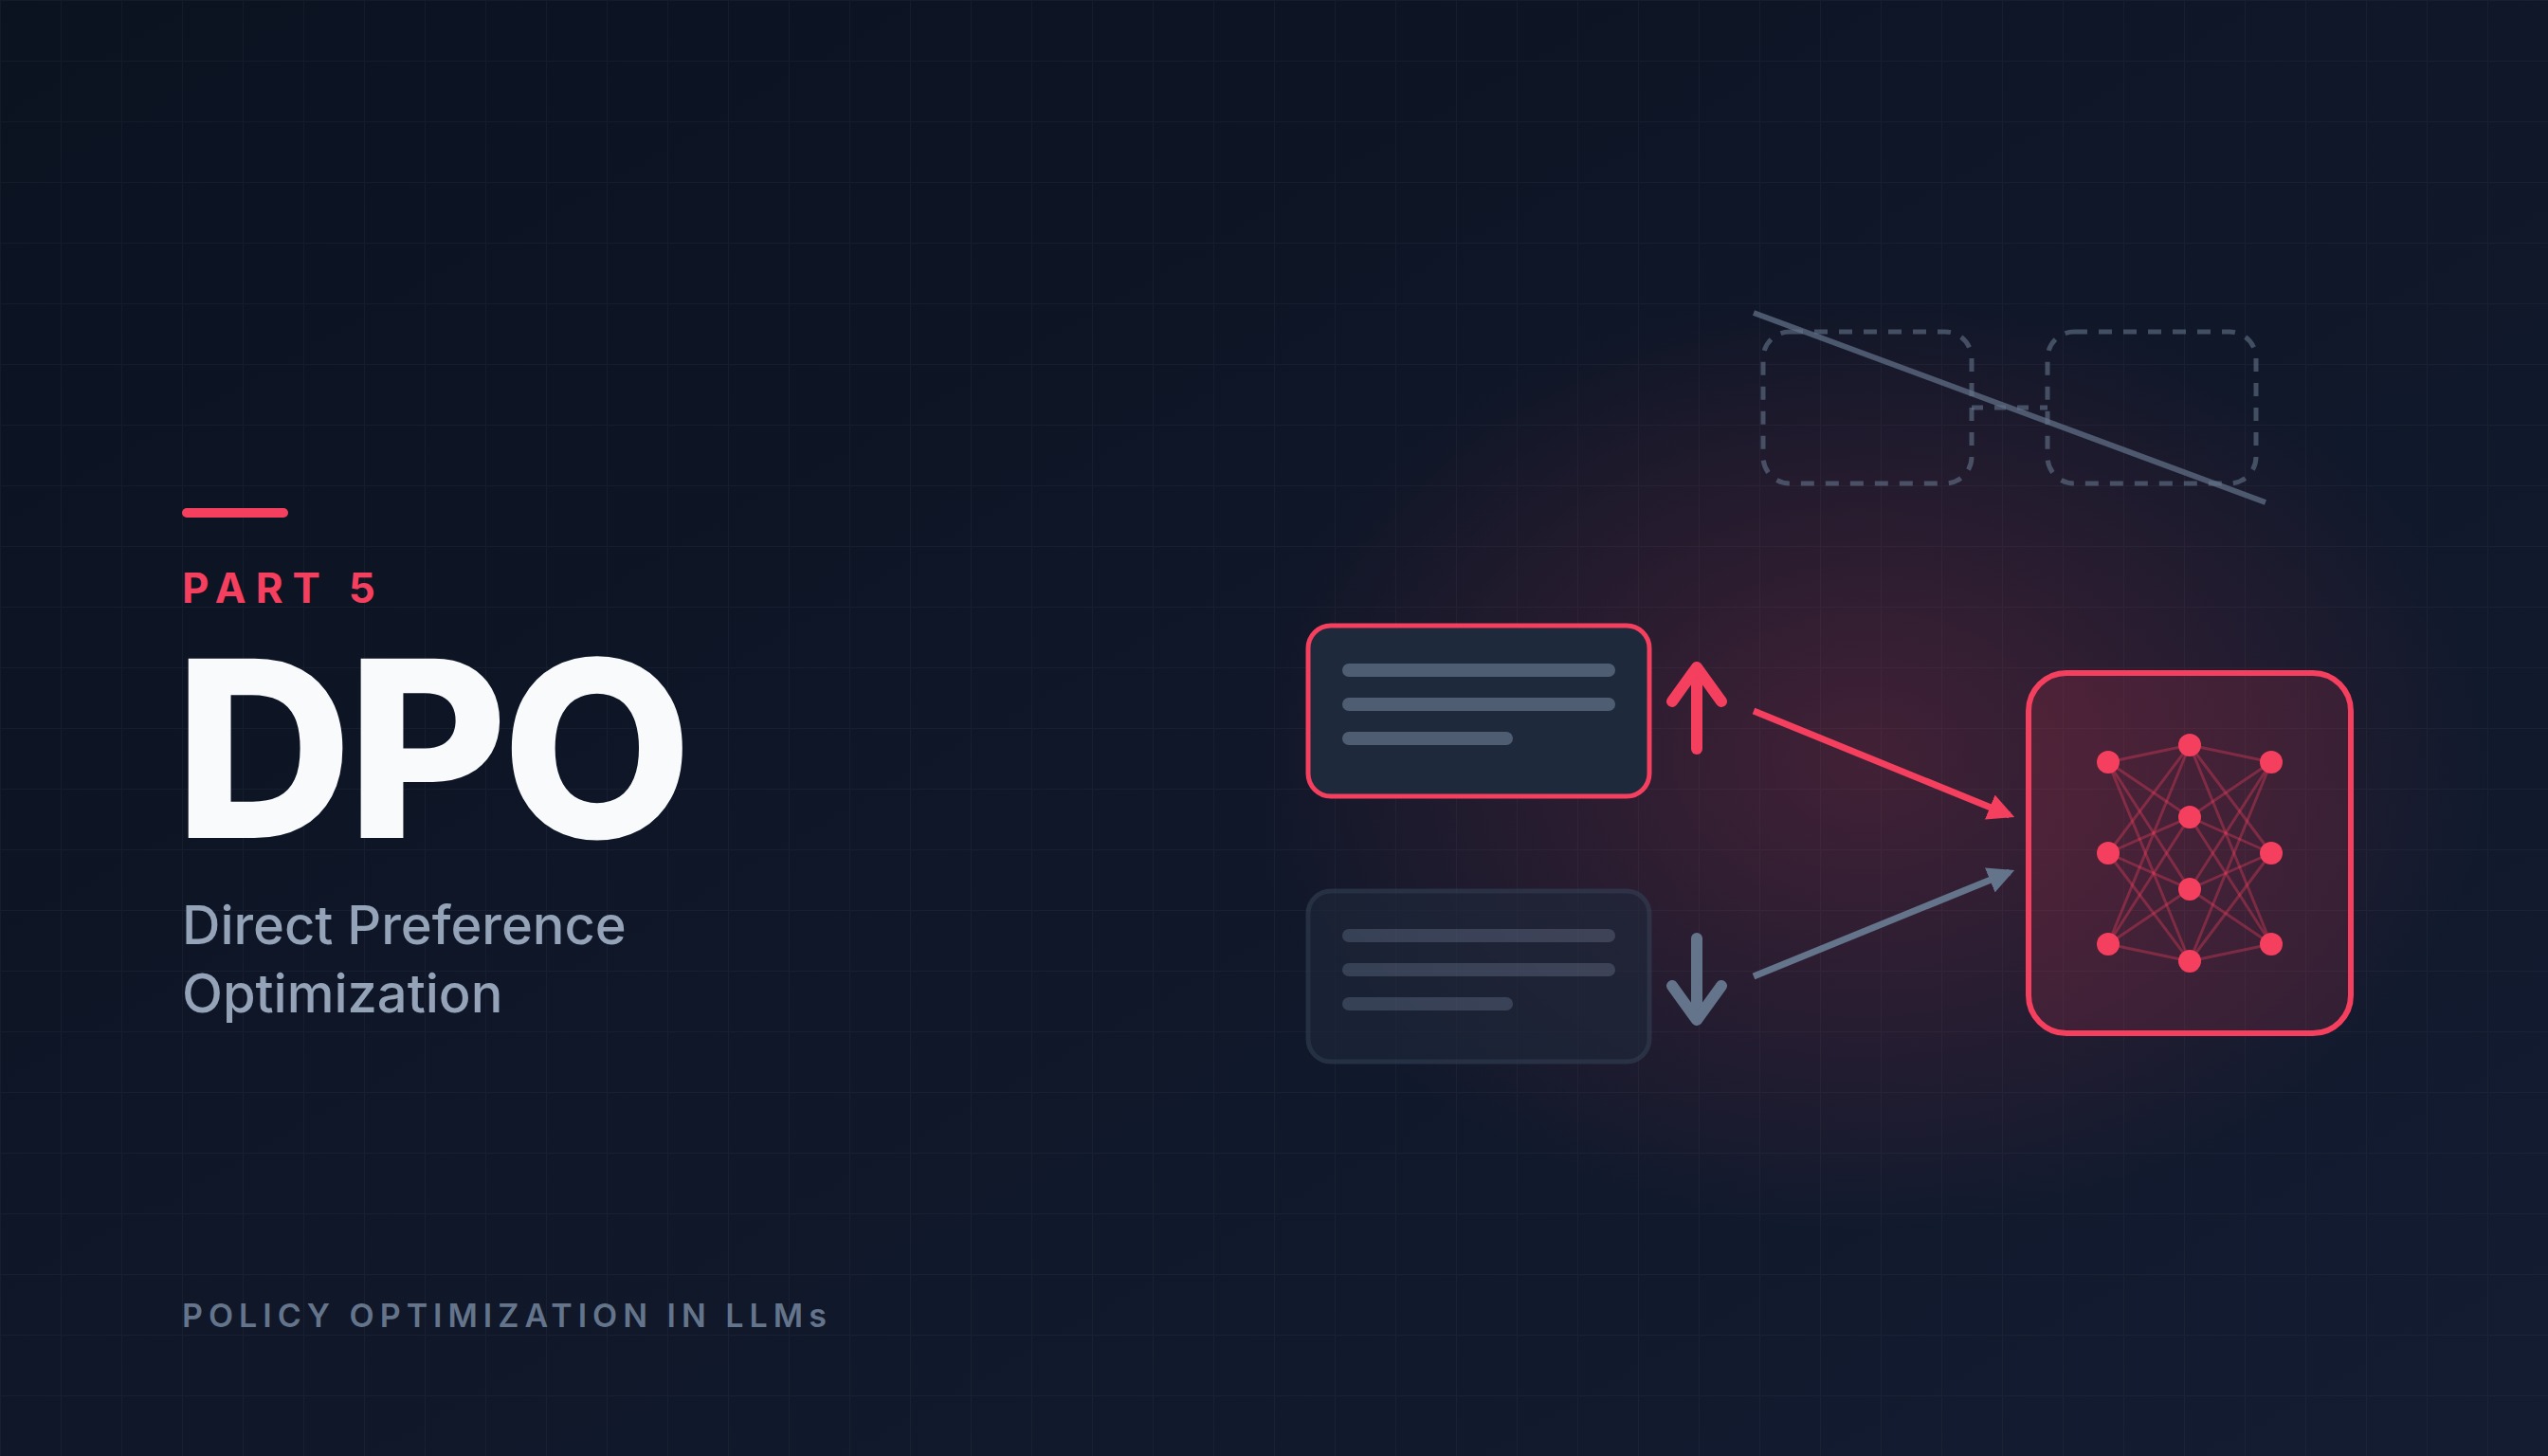
Part 4 ended with a question: if the preferences are what we actually care about, do we need the reward model and the RL loop at all? In 2023, Direct Preference Optimization (DPO) [1] showed that we do not. Its key observation is that the RLHF objective can be solved exactly, on paper. The solution tells us which policy is optimal for any given reward, and turning it around tells us which reward a given policy is optimal for. Putting that reward into the Bradley-Terry model gives a loss that trains the language model directly on the preference pairs, like a classifier, with no reward model, no value model, and no sampling during training. This is why the DPO paper is subtitled “Your Language Model Is Secretly a Reward Model”.
In this post, we follow that derivation step by step. We start from the RLHF objective, solve it to find the optimal policy, invert the solution to express the reward through the policy, and put that reward into Bradley-Terry to obtain the DPO loss. We then look at what its gradient does, what data it needs, how it compares with PPO in practice, and where it falls short.
The Starting Point: The RLHF Objective
We want a policy that does two things at once. It should produce responses with a high reward , and it should not move too far from the reference model , the frozen SFT model. This is exactly the objective of RLHF from Eq. (9) in Part 4:
RLHF optimizes this objective with PPO, one small step at a time, because it treats the policy as a large neural network that can only be improved by gradient steps. DPO asks a different question first: before training anything, what does the best possible policy for this objective look like? It turns out that this question has an exact answer.
Solving the Objective in Closed Form
To find the best policy, we rewrite Eq. (1) until it takes the form of a single KL divergence. A KL divergence is never negative and is zero only when its two distributions are equal, so once the objective has that form, its minimum can be read off directly. We get there in three steps: first we merge the two terms into one expectation, then we introduce a normalizing constant called the partition function, and finally we read off the optimal policy.
Merging the Two Terms
The KL divergence is itself an expectation over responses from , as we saw in Part 2:
Both terms of Eq. (1) are now expectations over the same responses, so we can put them under a single expectation. Then we turn the maximization into a minimization by flipping the sign, and divide by , which is positive and so does not change where the minimum is:
The reward term can also be written as a logarithm, since . Then the two logarithms combine into one:
This already looks like a KL divergence: the logarithm of divided by something, averaged over responses from . But there is one problem.
The Partition Function
A KL divergence compares two probability distributions, and the denominator above is not one. The reference probability is a probability, but it is multiplied by , which can be any positive number. If we add up this denominator over all possible responses , the total is generally not .
The fix is the same as for any set of positive weights: divide each one by their total. We call this total the partition function :
Suppose a prompt had only three possible responses, and the denominator gave them the weights , and . These are not probabilities, because they add up to . Dividing each by gives , and , which add up to and keep the same proportions as the original weights.
The sum runs over all responses because must be the same number for every response to the same prompt: a single total that every weight is divided by. If it changed from one response to another, dividing by it would change the proportions between responses instead of only rescaling them. For the same reason, depends only on the prompt , the reference model and the reward, and not on the policy we are optimizing.
Dividing by inside the logarithm and multiplying by it again, so that nothing changes, splits the objective into two parts:
The Optimal Policy
The denominator is now a valid probability distribution. We give it a name, :
With this name, the first term is exactly a KL divergence, and since does not depend on , it can be taken out of the inner expectation:
The second term does not depend on , so it does not affect which policy is best. The first term is a KL divergence, which is never negative and is zero only when the two distributions are identical (Gibbs’ inequality [2]). So the objective is minimized exactly when:
Eq. (4) is therefore the exact solution of the RLHF objective [1], [3]. It has an intuitive form: start from the reference model, and reweight every response by the exponential of its reward. Responses with a high reward become more likely, responses with a low reward less likely, and controls how strong the reweighting is. A large keeps close to ; a small lets the reward dominate.
This would seem to solve RLHF without any training. But we cannot use Eq. (4) directly. The partition function in Eq. (3) sums over every possible response to the prompt, and the number of possible responses grows exponentially with their length. For any realistic vocabulary and response length, this sum cannot be computed.
From the Optimal Policy to a Reward
DPO’s key move is to use Eq. (4) in the opposite direction. Instead of computing the policy from the reward, we express the reward through the policy. Taking the logarithm of both sides:
Solving for the reward, first multiplying by and then grouping the two log-probabilities:
This equation says that the reward of a response is, up to the term , times the log-ratio of how likely the optimal policy and the reference model make it. A response the optimal policy likes much more than the reference model did must have a high reward.
We still have the intractable , so this is not yet usable. But notice that depends only on the prompt, not on the response. That is exactly the kind of term the Bradley-Terry model ignores.
Putting the Reward into Bradley-Terry
Recall from Part 4 that the Bradley-Terry model gives each response a positive strength, , and lets each one win with a probability proportional to its strength. Dividing the numerator and the denominator by turns this into a sigmoid, as in Eq. (5) in Part 4:
The preference depends only on the difference of the two rewards. Now we substitute Eq. (6) for both rewards. Both responses answer the same prompt , so they share the same :
The partition function cancels completely. The probability that a person prefers over is now written entirely with quantities we can compute, the probabilities that two language models give to the two responses:
The DPO Loss
Eq. (8) describes human preferences through the optimal policy , which we do not know. So we do what we did with the reward model in Part 4: we replace the unknown quantity with a model and fit it to the preference data by maximum likelihood. The model here is our language model . Replacing with , taking the negative log-likelihood over the preference dataset , gives the DPO loss [1]:
This is the reward model loss from Eq. (6) in Part 4, with the reward replaced by
the implicit reward of the language model. Why is this replacement justified? Any policy is, by Eq. (6), the optimal policy for the reward (plus a term that depends only on the prompt and cancels in every comparison). So fitting with Eq. (9) is the same as fitting a reward model to the preferences, with one difference: the policy that is optimal for the fitted reward is itself. The two stages of RLHF, learning a reward and then optimizing a policy for it, collapse into a single supervised step. The language model is, in this sense, secretly a reward model.
Take a preference pair with . Language models usually give whole responses very small probabilities, so we work with log-probabilities. At the start of training, is a copy of , so both log-ratios are , the argument of the sigmoid is , and the loss is .
After some training, suppose the models give these log-probabilities:
| Log-ratio | Implicit reward | |||
|---|---|---|---|---|
| Preferred | ||||
| Rejected |
The argument of the sigmoid is , so and the loss is . The model has made the preferred response more likely and the rejected one less likely than the reference model does, and the loss has dropped accordingly.
What the Gradient Does
To see how DPO changes the model, write for the argument of the sigmoid, so that one term of the loss is . In Part 4, deriving Eq. (7), we found that the derivative of with respect to is , and . The reference model is frozen, so only the terms of have a gradient:
By the chain rule, and writing back in terms of the implicit rewards:
Gradient descent moves against this gradient, so each step makes the preferred response more likely and the rejected response less likely. This is the familiar form of the policy gradient from Part 1: increase the log-probability of a good response, decrease that of a bad one. The difference is in the weight. Instead of an advantage estimated by a value model, each pair is weighted by , the probability the model currently gives to the wrong ordering. When the implicit reward ranks the pair incorrectly, the weight is close to and the update is strong. When it already ranks the pair correctly by a wide margin, the weight is close to and the pair barely changes the model. In the example above, the weight is .
The DPO paper found this weight to be essential: a version without it, which simply increases and decreases by the same amount for every pair, caused the model to degenerate [1].
What Data DPO Needs
DPO trains on the same kind of data as the reward model in RLHF: a fixed dataset of triples , a prompt with a preferred and a rejected response. It does not need a person to judge every response during training, because it never generates responses during training at all. The dataset is collected once, before training, and DPO is an offline method.
The preference labels can come from several sources:
- People, as in RLHF: annotators compare two responses and pick the better one.
- AI feedback: a strong LLM acts as a judge and labels which response is better. This is called RLAIF (reinforcement learning from AI feedback), and it can produce preference data at a much larger scale than human annotation [4].
- Checkers: for math or code, a correct response can be the preferred one and an incorrect response the rejected one.
The responses themselves are usually generated by the SFT model, so that they come from roughly the same distribution as the reference model.
DPO in Practice
The full training procedure is short:
Compared with Stage 2 and Stage 3 of RLHF, almost everything is gone:
| RLHF with PPO | DPO | |
|---|---|---|
| Reward model | Trained separately | None (implicit in the policy) |
| Value model | Needed for the advantages | None |
| Sampling during training | New responses every iteration | None, fixed dataset |
| Models in memory | Four: policy, value, reward, reference | Two: policy, reference |
| Training | RL, many hyperparameters | Supervised, mainly and the learning rate |
The log-probabilities of the reference model do not change during training, so they can even be computed once before training starts, leaving a single model in memory.
In the DPO paper, this simple loss matched or exceeded PPO-based RLHF on sentiment control, summarization, and single-turn dialogue [1]. Because it is so much simpler, it quickly became a standard step in open models. Zephyr trained a small chat model with DPO on preferences labeled by an LLM [5], and Llama 3 used DPO in its post-training instead of PPO [6].
Limitations of DPO
DPO removes most of the complexity of RLHF, but its simplicity comes from strong assumptions, and they lead to clear limitations:
- It is offline. DPO learns only from a fixed dataset of responses written before training. As training goes on, the policy starts writing responses unlike any in the dataset, and DPO receives no feedback on them. RLHF with PPO scores the policy’s own new responses at every iteration. Online DPO, which keeps generating new pairs from the current policy and labels them with an AI judge, recovers much of this advantage [7].
- Both probabilities can go down. The loss depends only on the difference between the two implicit rewards. It can be lowered by making the rejected response much less likely, even if the preferred response also becomes less likely. In practice, this often happens: the probability of the preferred response falls during training, and the freed probability mass can move to responses that appear in neither, a problem called likelihood displacement [8], [9].
- It can overfit the preferences. If a pair is labeled the same way every time, the loss keeps pushing the gap between its implicit rewards toward infinity, and the KL penalty that was in the original objective no longer holds the policy back. IPO replaces the sigmoid loss with a squared one that targets a finite gap to avoid this [10].
Other variants change the loss in further ways: SimPO removes the reference model and normalizes the implicit reward by response length [11], and ORPO combines SFT and preference optimization into a single loss without a reference model [12].
DPO is a natural fit when the signal is a preference between two responses. But for tasks with an answer that can be checked, such as math or code, the most useful signal is a reward, and the model gains the most from being scored on its own, newly generated attempts. That brings back online reinforcement learning, and with it the problem of PPO’s expensive value model.
Can we keep online RL, but compute the advantage without a value model?
This is what GRPO does, and it is the topic of Part 6.
References
- Rafailov, R., Sharma, A., Mitchell, E., Ermon, S., Manning, C. D., & Finn, C. (2023). Direct Preference Optimization: Your Language Model is Secretly a Reward Model. NeurIPS.
- Cover, T. M., & Thomas, J. A. (2006). Elements of Information Theory (2nd ed.). Wiley.
- Korbak, T., Perez, E., & Buckley, C. L. (2022). RL with KL Penalties is Better Viewed as Bayesian Inference. Findings of EMNLP.
- Lee, H., Phatale, S., Mansoor, H., et al. (2024). RLAIF vs. RLHF: Scaling Reinforcement Learning from Human Feedback with AI Feedback. ICML.
- Tunstall, L., Beeching, E., Lambert, N., et al. (2023). Zephyr: Direct Distillation of LM Alignment. arXiv:2310.16944.
- Grattafiori, A., Dubey, A., Jauhri, A., et al. (2024). The Llama 3 Herd of Models. arXiv:2407.21783.
- Guo, S., Zhang, B., Liu, T., et al. (2024). Direct Language Model Alignment from Online AI Feedback. arXiv:2402.04792.
- Pal, A., Karkhanis, D., Dooley, S., Roberts, M., Naidu, S., & White, C. (2024). Smaug: Fixing Failure Modes of Preference Optimisation with DPO-Positive. arXiv:2402.13228.
- Razin, N., Malladi, S., Bhaskar, A., Chen, D., Arora, S., & Hanin, B. (2025). Unintentional Unalignment: Likelihood Displacement in Direct Preference Optimization. ICLR.
- Azar, M. G., Rowland, M., Piot, B., et al. (2024). A General Theoretical Paradigm to Understand Learning from Human Preferences. AISTATS.
- Meng, Y., Xia, M., & Chen, D. (2024). SimPO: Simple Preference Optimization with a Reference-Free Reward. NeurIPS.
- Hong, J., Lee, N., & Thorne, J. (2024). ORPO: Monolithic Preference Optimization without Reference Model. EMNLP.